Foundation Model Workspaces
GenMedia Creative Studio provides dedicated, interactive workspaces for exploring Google Cloud’s generative media foundation models directly. Before chaining models into multi-step creative pipelines, creators and engineers can use these direct workspaces to test prompts, compare model variants, inspect acoustic and visual telemetry, and curate reusable assets in the shared Studio Library.
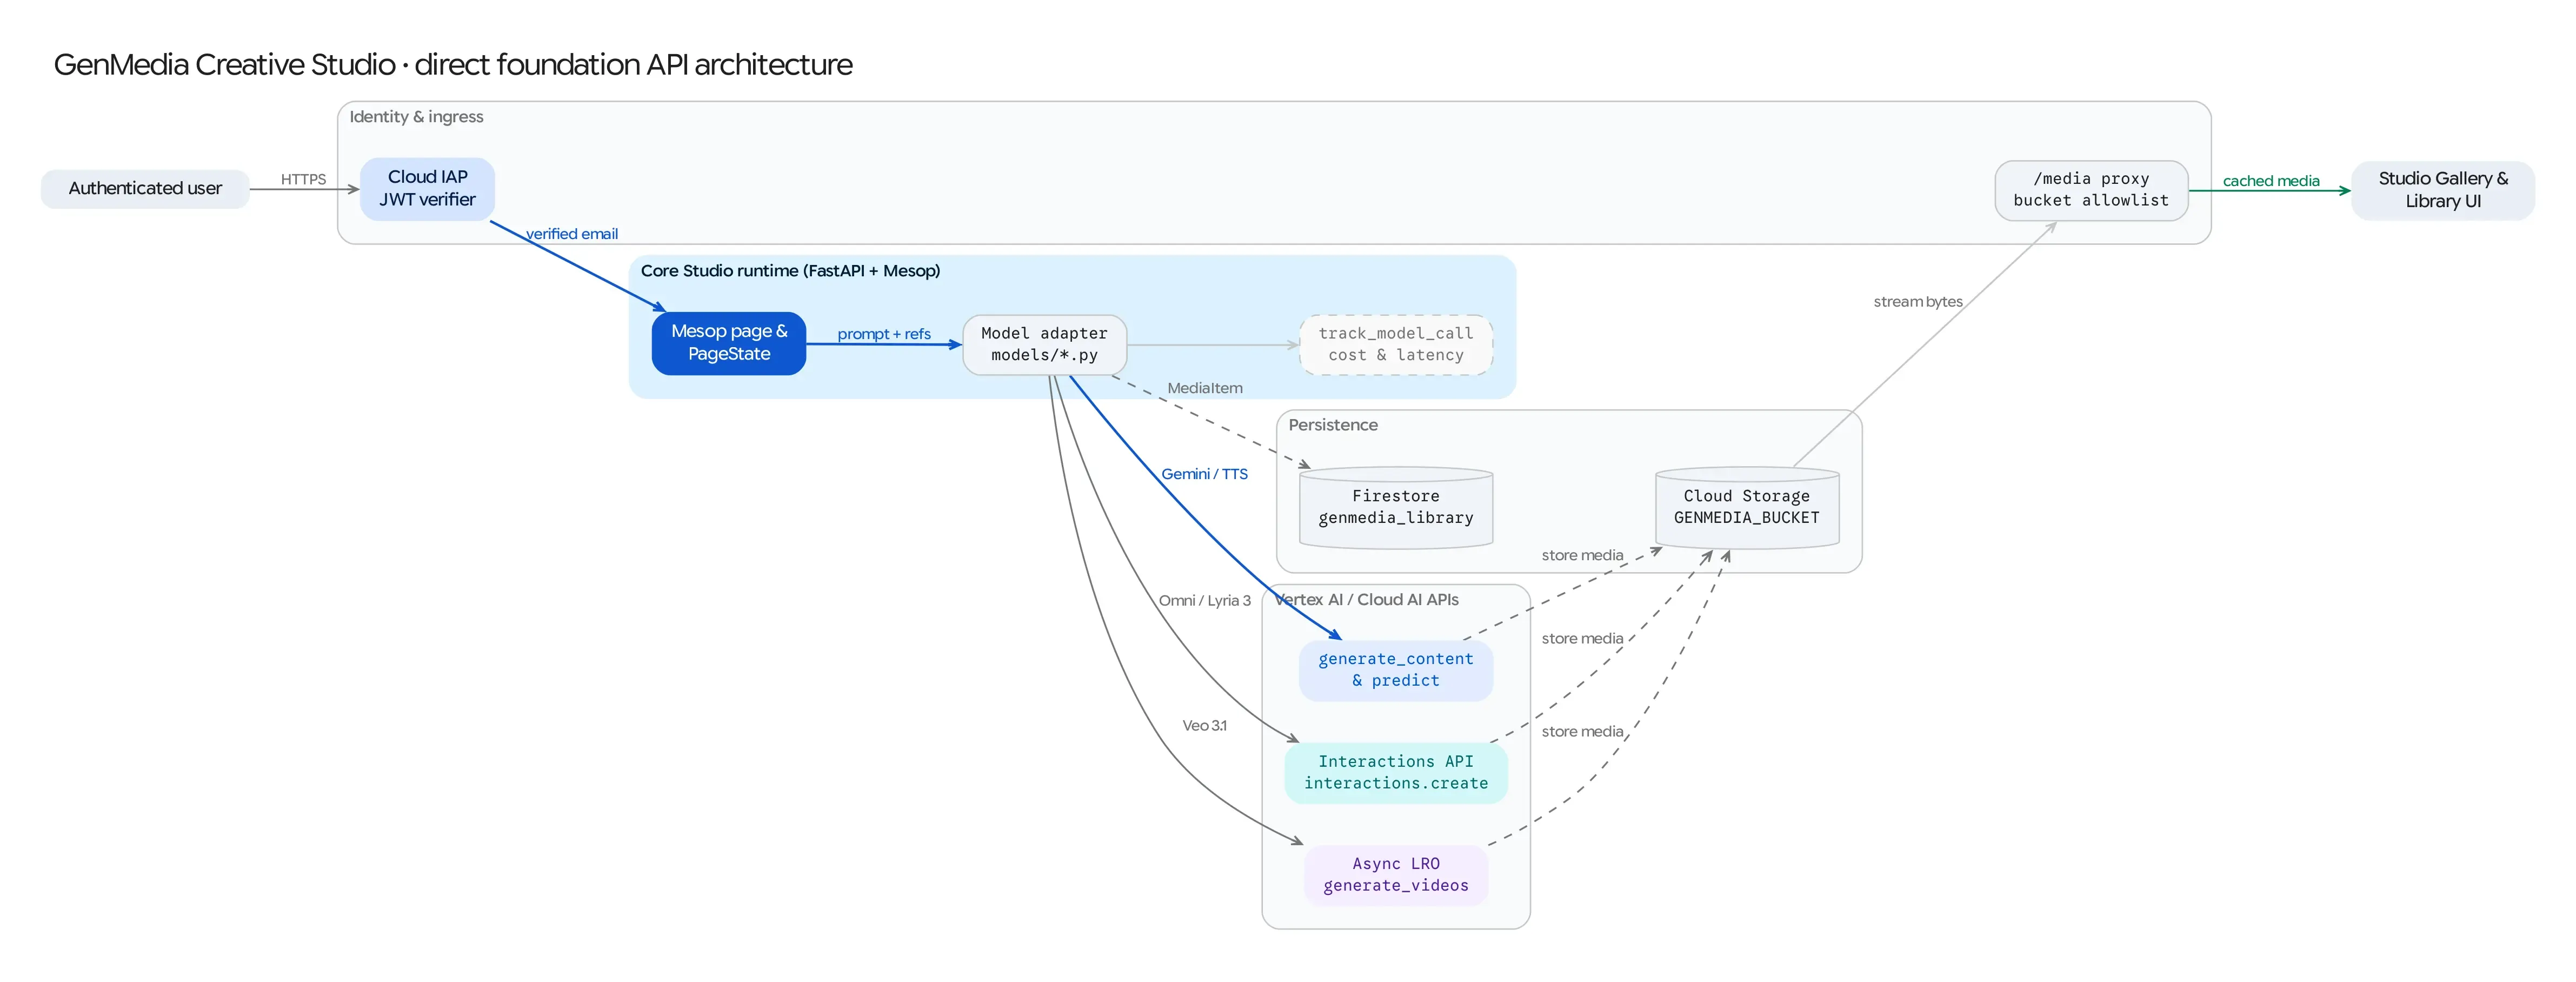
Direct Foundation Model Workspaces
Section titled “Direct Foundation Model Workspaces”| Workspace | Route | Primary Models (config/) |
Key Capabilities |
|---|---|---|---|
| Gemini Omni | /gemini-omni |
gemini-omni-1.1-flash-preview |
Interleaved multimodal text, image, and audio generation via the Vertex AI Interactions API (interactions.create) with resolution controls (360p–4k) and thought summaries. |
| Veo | /veo |
veo-3.1-generate-001, veo-3.1-fast-generate-001, veo-3.1-lite-generate-001, veo-3.0-*, veo-2.0-* |
Asynchronous long-running operation (generate_videos) video synthesis across Text-to-Video (T2V), Image-to-Video (I2V), First/Last Frame Interpolation, Reference-to-Video (R2V), and Video Extension. |
| Gemini Image Generation (Nano Banana) | /nano-banana |
gemini-3.1-flash-image-preview (Nano Banana 2), gemini-3.1-flash-image-lite-preview (2 Lite), gemini-3-pro-image-preview (Pro), gemini-2.5-flash-image |
Conversational image generation and multi-reference editing (up to 14 reference images), 1K/2K/4K output sizing, aspect ratio controls, and Google Search grounding. |
| Lyria | /lyria |
lyria-002, lyria-3-clip-preview, lyria-3-pro-preview |
Instrumental and vocal music synthesis supporting text prompts, custom lyrics, image conditioning, and C2PA provenance metadata preservation. |
| Gemini TTS | /gemini-tts |
gemini-3.8-flash-tts, gemini-3.8-flash-lite-tts, gemini-2.5-flash-tts, gemini-2.5-pro-tts |
Expressive single- and multi-speaker speech synthesis with natural-language style direction, inline vocal tags, and integrated Praat/Librosa acoustic analysis. |
| Chirp 3 HD | /chirp-3hd |
chirp_3 (Cloud Text-to-Speech API v1beta1) |
High-definition multi-locale speech synthesis with speaking rate controls, custom pause insertions, and custom phonetic pronunciations (IPA / X-SAMPA). |
| Gemini Writers Workshop | /gemini-writers-workshop |
gemini-3.5-flash / gemini-3.5-pro (MODEL_ID) |
Multimodal prompt engineering and narrative ideation workspace with customizable system instructions and persistent Firestore PromptTemplate libraries. |
Shared Request & Persistence Lifecycle
Section titled “Shared Request & Persistence Lifecycle”Every direct foundation model workspace in the core application (main.py) shares a unified security, storage, and telemetry architecture:
1. Identity & Ingress (main.py)
Section titled “1. Identity & Ingress (main.py)”- Cloud IAP JWT Verification: Incoming requests pass through
verify_iap_jwt(), which validates theX-Goog-IAP-JWT-Assertionheader against Google’s public keys (https://www.gstatic.com/iap/verify/public_key) and binds the verified user identity (user_email) intoapp.stateand MesopAppState. - Forwarded Host & CSRF Middleware:
TrustForwardedHostMiddlewarerewrites the internalHostheader fromX-Forwarded-Hostso Mesop’s WebSocket and/__ui__POST endpoints operate behind Cloud Run and Google Cloud Load Balancers without CSRF origin mismatches.
2. Mesop State & Model Adapters (pages/*.py → models/*.py)
Section titled “2. Mesop State & Model Adapters (pages/*.py → models/*.py)”- Each workspace maintains a page-scoped
@me.stateclass(stored instate/or the page module) that binds UI controls—model selectors, aspect ratios, reference media uploaders, and advanced parameter drawers—directly to Python event generators. - Dynamic Model Capabilities: Rather than hardcoding UI options, workspaces read declarative capability schemas from
config/(config/veo_models.py,config/gemini_image_models.py,config/lyria_models.py,config/gemini_tts.py) to dynamically adapt available resolutions, durations, reference image limits, and grounding toggles whenever the user switches models.
3. Vertex AI & Cloud AI API Dispatch
Section titled “3. Vertex AI & Cloud AI API Dispatch”Depending on the model family, adapters in models/ invoke one of three primary Google Cloud API patterns via google.genai.Client or google-cloud-texttospeech:
- Unary
models.generate_content/models.predict: Used by Gemini Image Generation (Nano Banana), Gemini TTS, Gemini Writers Workshop, and Lyria 2 (lyria-002). - Vertex AI Interactions API (
client.interactions.create): Used by Gemini Omni (gemini-omni-1.1-flash-preview) and Lyria 3 (lyria-3-clip-preview,lyria-3-pro-preview) for multimodal turn interactions and C2PA-signed media payloads. - Asynchronous Long-Running Operations (
models.generate_videos): Used by Veo (models/veo.py) and the FastAPI/api/veo/*router (routers/veo_router.py), polling operation status until video bytes or GCS URIs are finalized.
4. Cloud Storage, /media Proxy, and Firestore Telemetry
Section titled “4. Cloud Storage, /media Proxy, and Firestore Telemetry”- Cloud Storage (
common/storage.py): Generated images, audio tracks, and video clips (as well as user-uploaded reference assets) are persisted togs://<GENMEDIA_BUCKET>viastore_to_gcs(). - Authenticated
/media/{bucket_name}/{object_path}Proxy (main.py): To render private GCS objects in the browser without exposing public bucket ACLs, FastAPI exposes a streaming/media/proxy that enforces a strict bucket allowlist (GENMEDIA_BUCKET,VIDEO_BUCKET,IMAGE_BUCKET,MEDIA_BUCKET) and returns immutable cache headers (Cache-Control: public, max-age=3600). - Firestore Metadata (
common/metadata.py): Every completed generation constructs aMediaItemdataclass and writes it to the FirestoreGENMEDIA_FIREBASE_DBcollection (genmedia_libraryby default) viaadd_media_item_to_firestore(). This powers the cross-app Library (/library), provenance inspection, and one-click “send to workflow” actions. - Cost & Latency Analytics (
common/analytics.py): Model calls are wrapped in thetrack_model_call()context manager, recording model name, token/unit parameters, latency, and estimated cost.